
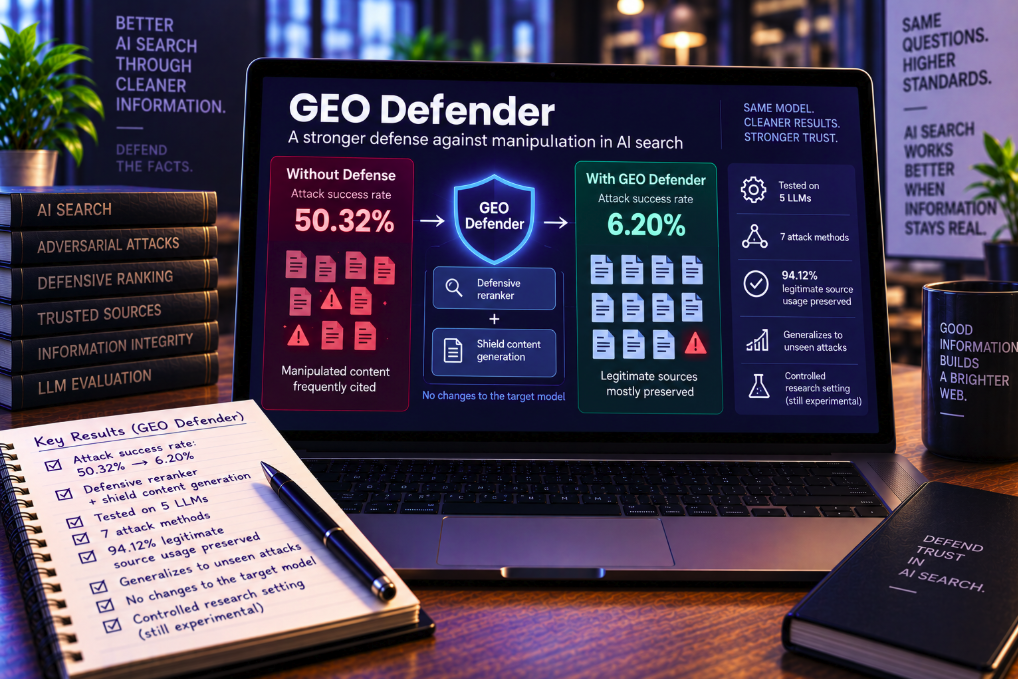
A new defense for generative search has reduced the success of malicious GEO manipulation from an average of 50.32% to 6.20% without fine-tuning the language model that ultimately generates the answer.
The system, called GEO Defender, is described in the September 2 arXiv paper “When Optimization Becomes Manipulation: Defending Generative Search against Malicious Generative Engine Optimization.” Across two closed-source and three open-source LLMs and seven GEO attack methods, the researchers report that the defense also retains 94.12% of legitimate evidence use and preserves answer quality.
The architecture is notable because it does not try to solve the problem by retraining every target LLM. Instead, it intervenes at two points in the generative-search pipeline: first by changing which documents survive reranking, and then by guiding the generator on how to use potentially manipulated sources that remain.
The result is one of the stronger experimental demonstrations so far that malicious GEO can be addressed at the retrieval and evidence-use layers rather than exclusively through model fine-tuning. It is also still a controlled research result, not proof that the same 6.20% attack-success rate would hold on Google AI Overviews, ChatGPT search, Perplexity or another live search product.
Malicious GEO attacks the evidence selection process
Generative engine optimization normally aims to make useful documents more likely to appear in AI-generated answers. Publishers can restructure information, improve clarity or present evidence in ways that make a page easier for a retrieval-and-generation system to understand and cite.
The security problem begins when those same mechanisms are deliberately used to manipulate source exposure. A malicious operator can rewrite a document to match the citation preferences of a generative engine and increase the probability that the target page enters the small evidence set used to produce the answer.
The paper argues that this threat is difficult to detect with simple factual verification because the rewritten document can remain factually consistent with its original. The manipulation can concern how strongly the document is favored and cited rather than whether it contains an obviously fabricated claim.
That makes the problem different from conventional misinformation filtering. The suspicious signals—clear structure, statistics, citations and authoritative presentation—can also be characteristics of excellent legitimate content.
GEO Defender targets two stages instead of changing the LLM
GEO Defender is built around a two-stage architecture aligned with the attack chain. The first component, Shield Reranker, operates before generation. The second, Training-Free Shield Generation, or TFSG, acts when the target LLM uses the selected evidence.
This separation reflects an important observation: a defense does not necessarily have to identify and eliminate every malicious document before generation. It can reduce the probability that manipulated documents reach the evidence set and separately make the generator more cautious about those that survive.
The target language model itself does not require fine-tuning. That potentially makes the approach more practical for systems that rely on proprietary or black-box LLM APIs whose parameters cannot be modified by the search provider.
However, “without fine-tuning the search model” should not be confused with “no learning anywhere.” Shield Reranker is a learned defensive component. What remains unchanged is the target LLM producing the final response.
Shield Reranker learns to demote manipulated rewrites
The first stage adds a defensive preference to the ranking process. Rather than replacing relevance ranking entirely, Shield Reranker learns a residual over a frozen base reranker.
Its objective is to push GEO-rewritten attack documents downward while preserving the underlying relevance judgments that allow useful sources to surface.
This is a delicate tradeoff. A security system that simply penalizes highly structured or citation-rich pages could suppress malicious GEO, but it would also punish publishers producing legitimately useful content.
The defensive reranker therefore attempts to learn the difference between a document being relevant to the query and a document being engineered to exploit the ranking and citation process.
That distinction is essential if generative search is to remain open to optimization without making optimization synonymous with manipulation.
The second stage creates a natural-language defense library
Shield Reranker cannot guarantee that every attack document disappears from the context. GEO Defender therefore adds Training-Free Shield Generation as a second line of defense.
TFSG distills defensive outcomes into what the researchers describe as a natural-language experience library. At inference time, that library guides the target LLM’s use of sources without requiring parameter updates to the model itself.
The approach is conceptually different from fine-tuning. Instead of teaching the model new behavior by changing its weights, the system supplies reusable defensive guidance externally when the model generates an answer.
This matters for deployment flexibility. A search provider can potentially change or upgrade its underlying LLM while retaining a separate defensive layer around evidence selection and source use.
Average attack success falls from 50.32% to 6.20%
The headline result comes from experiments spanning five target LLMs—two closed-source systems and three open-source models—and seven malicious GEO attack methods.
Without GEO Defender, the average attack success rate is 50.32%. With the full defense, it falls to 6.20%.
That is an 44.12 percentage-point absolute decline, leaving the defended attack success rate at roughly one-eighth of the undefended level.
The researchers also measure semantic influence, an additional signal intended to capture how much an attack changes the generated answer rather than merely whether it crosses the binary attack-success threshold. Their results similarly indicate a large reduction in malicious influence under the combined defense.
The scale of the improvement suggests that attacking the ranking and source-use stages together can be substantially more effective than treating malicious GEO as a conventional unsafe-output problem.
The system retains 94.12% of benign evidence use
Attack suppression alone would be a weak result if the system achieved it by refusing to use web sources. GEO Defender is therefore evaluated on how much legitimate evidence remains available to the answer generator.
The paper reports 94.12% retention of benign-evidence use under the full defense.
That metric is particularly important in generative search because the objective is not merely to stop an attacker. The system still needs to retrieve and synthesize useful information from publishers, documentation, research and other web sources.
A defense that aggressively removes anything resembling GEO-optimized content could improve a security benchmark while degrading the search product itself. Preserving most benign evidence indicates that the reported attack reduction is not simply the consequence of broadly shutting down retrieval.
Answer quality remains essentially preserved
The researchers also report that overall answer quality remains stable under the defense.
This provides a second check against over-filtering. A reranker can make a system safer by removing documents, but removing too many relevant documents can make the generated response incomplete or less useful.
GEO Defender’s design tries to preserve the original relevance signal while adding a defensive correction rather than replacing the ranking objective with a binary attack detector.
The TFSG layer then regulates how surviving evidence is used instead of forcing the generator to refuse whenever uncertainty appears.
In the controlled evaluation, that combination appears to provide a much stronger security-utility tradeoff than simply suppressing large portions of the evidence pool.
The two stages address different failure points
The architecture is useful because malicious GEO has more than one opportunity to influence an answer.
The first opportunity is exposure. If an optimized attack document rises in the ranking and enters the limited context window, it gains a chance to affect the response.
The second is utilization. Even if the document enters the context, the generator still decides how heavily to rely on it and whether to cite it.
Shield Reranker primarily attacks the first problem. TFSG addresses the second. The paper’s ablation results indicate that both components can reduce attacks independently, while the combined system performs better by covering both stages.
This suggests a broader principle for AI-search security: defenses may be more robust when they are distributed across the evidence pipeline instead of relying on a single classifier or final-output safety check.
The defense generalizes to attack methods it did not see during construction
One of the more important claims is that GEO Defender is not evaluated only against the same attack methods used to construct its defensive behavior.
The researchers include attacks excluded from the construction process and report that the defense continues to suppress manipulation on those unseen methods.
This matters because a security mechanism that merely memorizes the stylistic signatures of known GEO rewriting systems would be fragile. Attackers could switch optimization techniques and recover much of their success.
Generalization to unseen attacks provides evidence that the system is learning or encoding broader defensive patterns rather than only blocking exact templates.
It does not establish robustness against an adaptive attacker who knows GEO Defender’s design and deliberately optimizes against it, but it is a stronger test than evaluating exclusively on familiar attack families.
Five LLMs make the result broader than a single-model demonstration
The experiment includes both open and closed models, reducing the likelihood that the headline result is merely an artifact of one LLM architecture.
This is especially relevant for TFSG because the second stage interacts with the model’s source-use behavior. A defensive experience library that worked only with the model used to create it would have limited practical value.
The paper reports transfer across model configurations, suggesting that at least some of the defensive guidance can remain useful when the underlying generator changes.
That said, five models are still a research sample. Commercial generative-search systems combine LLMs with proprietary indexes, ranking stacks, retrieval heuristics, source-quality systems and product-specific prompting that are not reproduced by simply swapping the generator in a laboratory pipeline.
This attack model differs from pure misinformation poisoning
GEO Defender should also be distinguished from research focused on information-distorting GEO, where an attacker changes the factual content of a document to inject false claims into generated answers.
The threat in this paper centers on malicious optimization of citation exposure. Attack documents can remain factually consistent with their originals while being rewritten to exploit the generative engine’s preferences.
That is why fact verification and perplexity filtering are weak fits for the problem. A fact checker can find nothing wrong if the content remains factually consistent, while a perplexity filter can fail because the rewritten prose remains natural.
The defense instead tries to identify and neutralize the manipulation pattern within ranking and evidence use.
This distinction matters when comparing GEO security benchmarks. “Attack success” can mean different things depending on whether the adversary is trying to promote a source, distort a factual claim or inject instructions into the model.
The study does not prove production search engines are currently 50% vulnerable
The 50.32% baseline should not be interpreted as the real-world attack success rate of commercial AI search.
The authors evaluate GEO Defender in a controlled experimental framework designed to make defensive methods comparable. Production products have hidden components that can change both the attack surface and the effectiveness of a defense.
Google may apply source-quality systems before an AI Overview is generated. ChatGPT search can use its own retrieval stack. Perplexity has different ranking, crawling and citation mechanisms. None of those systems is directly audited by the paper.
The 50.32% and 6.20% figures therefore describe the benchmark conditions established by the researchers, not universal probabilities that apply whenever someone attempts GEO manipulation on the open web.
Nor is GEO Defender a finished production security layer
The research shows that the proposed architecture can work under the tested conditions. It does not establish that GEO Defender is ready to operate at internet scale.
Production systems have to handle rapidly changing pages, multilingual content, multimodal sources, spam networks, legitimate SEO and GEO experimentation, breaking news and adversaries that deliberately probe defenses.
A reranker also has to operate within strict latency and computational constraints. Adding defensive processing can be inexpensive in a benchmark but materially affect a high-volume consumer search service.
Most importantly, attackers adapt. Once the defensive preferences of a system become discoverable, malicious optimizers can search for content that preserves their ranking advantage while avoiding the patterns the reranker penalizes.
The unseen-attack results are encouraging, but they are not equivalent to a live adversarial contest against attackers optimizing specifically for GEO Defender.
The paper points toward a modular security model for AI search
The strongest architectural idea may be that generative-search security does not have to reside entirely inside the foundation model.
Search products already separate indexing, retrieval, ranking and generation. GEO Defender treats those layers as security controls too.
A provider can defend the evidence set before generation through reranking. It can then influence source usage through external inference-time guidance. Neither intervention requires changing the weights of the target LLM.
That modularity can be valuable in a market where model providers and search providers are not always the same company. A business building a search product on top of a third-party API may have no ability to fine-tune the underlying frontier model but can still control retrieval, reranking and prompt context.
GEO Defender suggests that those layers may be sufficient to make a large difference against at least some forms of manipulation.
Legitimate GEO and malicious GEO are becoming a ranking-policy problem
The deeper challenge is deciding when optimization crosses the line into manipulation.
Web publishers have always adapted content to ranking systems. Traditional SEO changes titles, internal links, structure and wording to make pages easier for search engines to understand and rank. GEO similarly encourages publishers to make content easier for generative systems to retrieve and cite.
Many of the features an attacker can amplify—clarity, authoritative tone, statistics and citations—are also features a high-quality source may naturally contain.
This means a generative-search defense cannot simply penalize content for being optimized. It needs a policy for distinguishing improvements that make evidence more useful from transformations whose primary effect is to exploit the engine’s source-selection preferences.
Shield Reranker’s residual design is one attempt to preserve relevance while adding that security preference.
The next GEO battle may happen before the answer is written
Most public discussion of AI safety focuses on the final generated text: whether the model hallucinates, produces harmful instructions or refuses appropriately.
Malicious GEO shifts attention upstream. If the wrong evidence enters the context because ranking has been manipulated, the generator starts from a compromised information environment.
GEO Defender’s results support the idea that protecting generative search may require controlling both which evidence reaches the model and how the model uses it.
Under the paper’s controlled conditions, that two-stage approach reduces average attack success from 50.32% to 6.20%, preserves 94.12% of legitimate source use and requires no fine-tuning of the target LLM.
Those numbers should remain attached to the benchmark rather than projected onto live search engines. But the architectural lesson is broader: AI-search security may not require waiting for a safer foundation model. Some of the most effective defenses could sit between the web and the model, where sources are selected, ranked and turned into evidence.