
Generative Engine Optimization is often framed as a rewriting problem: make a page clearer, add statistics, sound more authoritative or restructure the copy, then hope an AI answer engine cites it more often. A new research paper proposes a different starting point. Before changing the content, diagnose where the page is actually losing the citation.
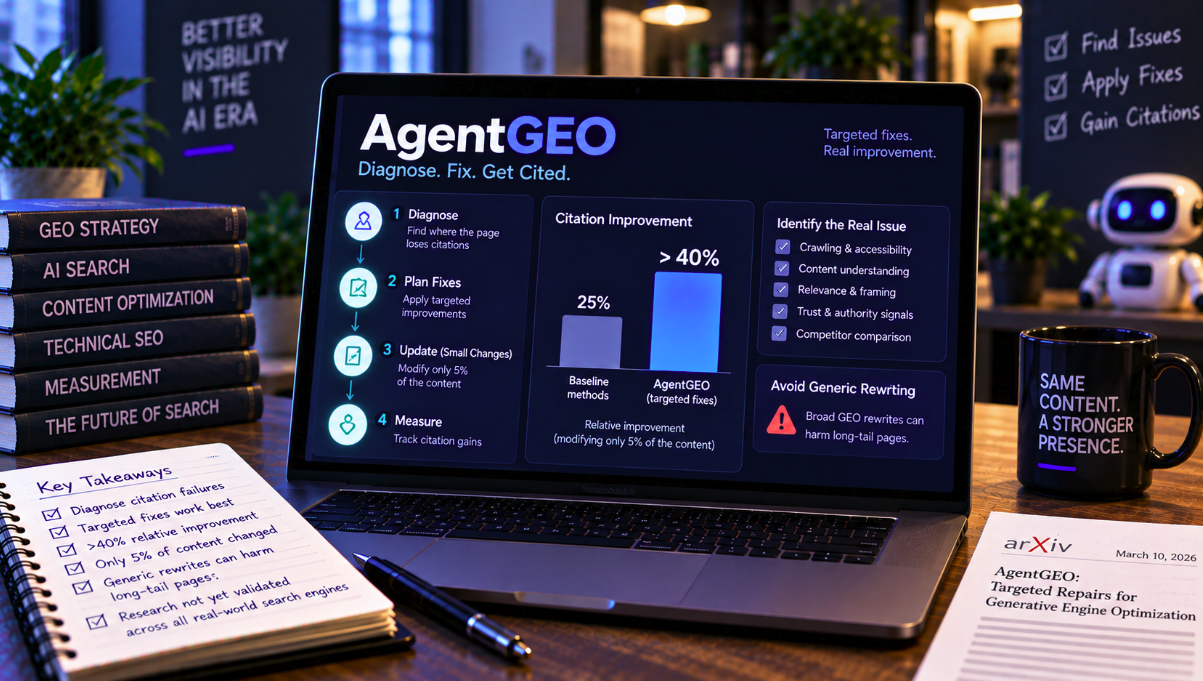
That is the premise of “Diagnosing and Repairing Citation Failures in Generative Engine Optimization,” an arXiv preprint submitted on March 10 by Zhihua Tian, Yuhan Chen, Yao Tang, Jian Liu and Ruoxi Jia. The researchers introduce AgentGEO, an agentic system that identifies likely failure modes, chooses a targeted repair from a tool library and tests whether the intervention restores citation. In their controlled experiments, the authors report more than a 40% relative improvement in citation rate while modifying about 5% of the original content, compared with roughly 25% changed by baseline optimization methods.
The headline is compelling because it challenges the assumption that a page invisible to an answer engine necessarily needs a broad editorial makeover. The paper instead models citation as a pipeline with several places to fail. A technically inaccessible page, a page whose important passage is truncated, a document missing the entity required by the query and a perfectly relevant page facing a dominant competitor may all end with the same observable result—no citation—but rewriting all four with the same generic GEO recipe is unlikely to address the same underlying problem.
AgentGEO treats non-citation as a diagnosis problem
The researchers built a taxonomy from 949 contrastive pairs in which a retrieved but uncited webpage was compared with a cited competitor for the same query. Their top-level analysis attributes 10.1% of failures to technical integrity, including access, JavaScript, parsing and signal-to-noise problems; 62.2% to semantic alignment, such as intent divergence, contextual gaps, stale information or localization mismatch; and 27.1% to content-quality issues including information scarcity, fragmentation, verbosity and weak structure. A small 0.6% category covers systemic exclusion such as competitive redundancy and context-window truncation.
AgentGEO uses those distinctions operationally. Given a page that is not being cited, it compares the document with successful competitors, diagnoses the most plausible disadvantage, applies a specialized intervention and then checks the citation outcome. If the page still fails, the agent can diagnose again and try another repair while retaining memory of previous attempts. The conceptual shift is important: instead of asking which GEO tactics are generally associated with visibility, the system asks which specific bottleneck prevents this particular document from crossing the citation threshold.
The benchmark is also designed to make simple query overfitting harder. The authors introduce MIMIQ, a document-centric dataset built from 204 ClueWeb22 webpages, each associated with 60 queries spanning different intents, personas and phrasings. Twenty queries per page are used for optimization and 40 are held out for evaluation, producing 12,240 queries overall. Separate out-of-distribution and HTML-focused variants test whether changes generalize to unseen user behavior and whether the optimizer can handle structural problems rather than merely rewriting visible prose.
Small targeted changes beat broad rewrites in the controlled setup
In the paper’s in-context generation experiment, the unoptimized baseline achieved a 56.58% citation rate, AutoGEO reached 68.80%, and AgentGEO reached 79.52%. Under a second “attribute-first-then-generate” citation method, the corresponding rates were 60.20%, 65.97% and 70.00%. The authors summarize the overall result as more than 40% relative citation improvement for AgentGEO while touching only about 5% of page content, versus approximately 25% for the baseline optimization approaches.
The preservation result may matter as much as the citation gain. Broad AI rewriting can alter terminology, remove niche details, flatten a publication’s voice or accidentally weaken information that serves queries outside the optimizer’s immediate target. AgentGEO’s premise is that if the failure is localized, the repair should be localized too. A parsing problem calls for a structural fix; an entity gap calls for supplying the missing context; excessive boilerplate calls for improving signal-to-noise. None automatically justifies rewriting the rest of a page that may already work well.
The topic analysis provides a warning against universal GEO templates. AutoGEO performed worse than the vanilla baseline in several categories, particularly when pages already had high citation rates, which the authors interpret as evidence that generic rules can damage long-tail content. Even AgentGEO was not uniformly positive: health pages began with citation rates around 80%, leaving little headroom, and the researchers found cases where optimization removed domain-specific information and reduced citation likelihood. The result is a useful counterweight to the idea that every page becomes more “AI friendly” when subjected to the same readability, authority or statistics checklist.
The 40% figure is a research result, not a live-search promise
The most important limitation is experimental realism. Commercial generative-engine pipelines are proprietary, so the researchers constructed a controlled simulation using standard retrieval and generation components with explicit citation instructions. They also evaluated GPT and Claude as generator models on a 50-page subset: AgentGEO reached a 79.52% citation rate versus AutoGEO’s 68.80% with GPT, and 54.80% versus 46.80% with Claude. Those results suggest the approach is not tied to a single generator, but they are not equivalent to testing the full live retrieval, ranking, extraction and citation systems behind ChatGPT Search, Google AI Overviews, Perplexity or other commercial products.
The authors themselves identify validation against commercial engines as future work. That means the reported improvement should be read as evidence that diagnostic repair can outperform generic rewriting under the paper’s benchmark and controlled citation pipelines, not as a forecast that editing 5% of a production webpage will raise real-world AI citations by 40%. Live engines can use undisclosed retrieval signals, domain-level priors, freshness systems, safety filters and citation policies that the experimental environment cannot reproduce.
The study also finds a harder boundary for content optimization. In one 50-page failure analysis, citation across training queries increased from 57.0% to 83.7%, yet 163 queries remained uncited after optimization. The researchers describe cases where the page itself was successfully improved but the engine continued to prefer dominant sources, such as established education platforms over a university course page. Their interpretation is that some citation disadvantages may operate at a domain or competitive level and cannot simply be repaired by editing the target document.
For GEO practitioners, that may be the paper’s most durable idea. A missing citation is an outcome, not a diagnosis. Before commissioning another wholesale AI rewrite, teams can ask whether the failure is technical access, parsing, information placement, intent alignment, missing context, content density or competition that page-level editing may never overcome. The exact AgentGEO gains still need validation on commercial engines, but the research makes a strong case for a less destructive optimization principle: find the failure first, then change only what the evidence says is broken.