
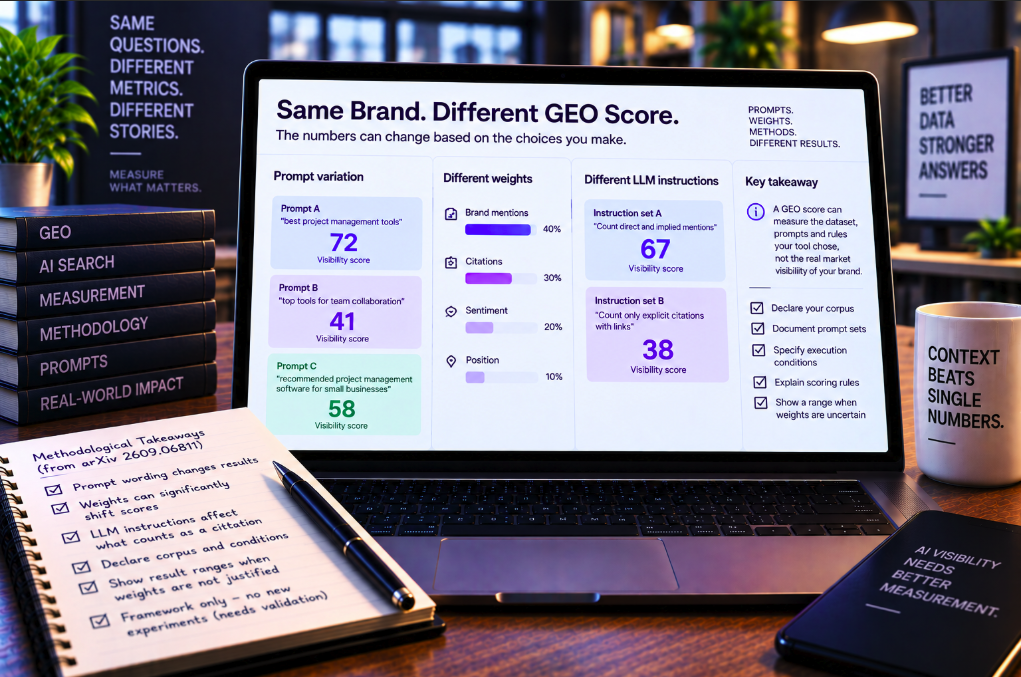
A GEO visibility score can look like a measurement of the AI search market while actually describing something much narrower: the collection of prompts, weights and scoring rules chosen by the tool that produced it.
That is the central warning in a new methodological paper, “Measuring GEO Visibility: Prompt Corpora Define the Answer Market,” submitted to arXiv on September 6 by Olivier Martinez. The paper argues that the prompt set used in a generative engine optimization benchmark is not a neutral window onto brand visibility. It helps define the very population of answer opportunities over which visibility is calculated.
The implication is uncomfortable for an industry increasingly filled with dashboards that compress AI mentions and citations into a single score. Two tools can query the same model about the same brand and return different visibility numbers without either calculation necessarily being arithmetically wrong. They may simply have constructed different markets to measure.
The paper calls this constructed population an “answer market.” Its broader argument is that GEO measurement needs to disclose that market explicitly rather than presenting a score as if it automatically represented how customers encounter brands across real AI usage.
A prompt corpus is not automatically a sample of customer demand
Most AI visibility systems begin with a panel of prompts. The tool sends those prompts to ChatGPT, Gemini, Claude, Perplexity or another generative engine and records whether a brand or source appears, is cited or is recommended.
The results are then aggregated into a score. That workflow sounds straightforward, but the paper argues that every step embeds assumptions about what matters.
If a benchmark contains mostly “best software” prompts, it measures visibility in comparison-style answers. If it contains brand-specific verification questions, it measures something different. A corpus centered on U.S. English-language purchasing scenarios is not automatically representative of users researching the same category in France, Japan or Brazil.
Even when every prompt came from a real human, the sample can still be unrepresentative. Customer-support logs, internal site search, public chatbot conversations and buyer interviews all originate with people, but they reflect different populations and objectives.
Calling prompts “real” therefore does not establish that their frequency matches the market a visibility score claims to represent.
The paper calls this constructed population an “answer market”
Martinez defines the answer market as the weighted set of situations in which an engine has an opportunity to display a source, citation or brand mention.
The word “weighted” is crucial. A benchmark does not merely decide which questions exist; it decides how much each question matters to the final score.
A tool might assign equal importance to every prompt. Another could weight prompts by estimated search demand, commercial value, customer journey stage or a client’s strategic priorities. A third could have many paraphrases of one question family and accidentally give that topic greater influence simply because it occupies more rows in the dataset.
All of those designs can produce legitimate metrics if their target is clearly stated. The problem arises when a strategic benchmark or a uniformly weighted test panel is presented as though it estimates actual population-level AI usage.
As the paper puts it, unknown frequencies do not become known simply because taking a simple average is convenient.
Prompt wording can change the system being observed
Generative search adds a complication that conventional web analytics does not have to the same degree: the measurement instrument can alter the thing being measured.
Changing a prompt from “best project management software” to “recommended project management software for a small nonprofit” can change retrieval, competing documents and the generated answer. Even apparently cosmetic rewrites can sometimes alter model behavior.
This means prompt wording is not just a label attached to an underlying fixed query. It is an input into the generative system.
The paper draws on broader research into prompt sensitivity and language-model evaluation to argue that formulation policies should therefore be part of the documented protocol. But it avoids the simplistic conclusion that every response difference is a measurement defect.
Some reformulations legitimately change the information need. Adding a location, budget, business size or use case should sometimes change the recommendation. A good benchmark needs to distinguish between variations that are intended to express the same situation and variations that intentionally create a different one.
The scoring LLM can introduce a second prompt problem
Many GEO measurement pipelines do not rely solely on exact string matching. They use another language model to inspect an answer and decide whether a brand was mentioned, recommended or cited.
That creates a second layer of prompt dependence.
The first prompt is sent to the AI system being measured. The second is the instruction sent to the LLM judge that evaluates the resulting answer.
The judge might be told to count only explicit brand mentions. Another instruction could count implied references. One rubric might distinguish a positive recommendation from a negative mention, while another could treat both as visibility. A citation detector might require a direct linked source, while a looser instruction might infer attribution from surrounding text.
The paper argues that changing this judging instruction can alter the score even when the saved answer being evaluated is identical.
For that reason, a reproducible GEO protocol should disclose the judge model, rubric, instruction and relevant variants rather than treating automated scoring as an invisible implementation detail.
Weights alone can dramatically change an aggregate number
The paper includes a reproducible arithmetic demonstration using previously published aggregate data from three query subcorpora in earlier research. Without changing the activation rate inside any of the subgroups, two different weighting schemes produce overall generative-answer activation rates of 39.7% and 70.5%.
This example needs an important qualification: it measures whether a generative answer activates, not brand visibility. Martinez is using the published data to demonstrate the mathematical consequence of aggregation choices, not claiming to have discovered that a real company’s GEO score can be moved between those two percentages.
The lesson is nevertheless directly relevant to GEO dashboards. An overall percentage is inseparable from the distribution used to aggregate its component situations.
If informational questions receive most of the weight, a brand strong in informational answers may look dominant. If commercial comparisons receive more weight, a different brand can rise. Neither score is inherently the “real” one unless the weighting scheme has a defensible relationship to the target market or a clearly declared strategic objective.
Reweighting can even reverse which system appears better
A second example in the paper makes the point more starkly. Martinez constructs two fictional systems that perform differently across open-ended discovery and named-verification scenarios.
When discovery receives relatively little weight, System A scores higher. When discovery receives most of the weight, System B wins. The ranking reverses because each system is stronger in a different category.
This is a mathematical example, not an experiment with real GEO products, and the paper explicitly says ranking reversal is not inevitable. If one system performs better in every category, applying the same nonnegative weights cannot reverse the ordering.
But when performance profiles cross, the choice of weights can determine which tool, brand or engine appears superior in the aggregate.
A leaderboard can therefore be partly a statement about the evaluator’s priorities.
More prompts do not automatically solve representativeness
The industry’s intuitive response to benchmark uncertainty is often to increase the number of prompts. Larger samples can reduce some forms of statistical noise, but the paper argues that volume alone does not establish market validity.
A million synthetically generated buyer prompts can provide broad controlled coverage while still having frequencies unrelated to actual customer behavior. Likewise, thousands of real chatbot conversations can represent the users of a particular interface rather than the entire addressable market.
The relevant question is not simply whether a corpus is large, diverse or human-generated. It is how the corpus was produced and what population the resulting score is supposed to describe.
That distinction becomes particularly important when vendors market a visibility score as a share of “AI search” rather than a share of a defined benchmark.
Single-turn prompt lists may miss how people actually use assistants
Conversational AI also complicates the unit of measurement. A benchmark consisting only of initial prompts measures first-answer opportunities. Real users often refine questions through follow-ups.
A shopper might begin with a broad category question, then add budget constraints, ask about two competing brands and finally request a retailer recommendation. The visibility opportunities created in the fourth turn are not represented by a dataset that records only the first question.
The paper therefore distinguishes prompt corpora from interaction trajectories. Neither is universally superior; they measure different targets.
If a GEO platform claims to estimate visibility across customer journeys, it should explain whether its corpus actually contains those journeys or merely independent one-shot prompts.
Location, language and assumed knowledge belong in the protocol
Generative answers can vary according to geography, language, conversation history and information already available to the system. Those execution conditions can influence which sources are retrieved and which brands are considered relevant.
A visibility benchmark that repeatedly runs U.S.-based English prompts in fresh sessions may be useful for that specific environment. It does not automatically estimate exposure for multilingual users, logged-in customers or people with longer conversation histories.
The proposed framework therefore treats execution conditions as part of the measurement protocol rather than background technical details.
For vendors, this implies that disclosures such as model version, date, location, language, account state, conversation context and repetition strategy can be essential for interpreting a score.
The paper proposes score ranges when the weights cannot be justified
One of the more practical proposals is to stop forcing every GEO benchmark into a single number when the underlying weights are uncertain.
If several weighting schemes are plausible, the paper proposes reporting a set of admissible scores or a sensitivity envelope showing how the result changes across defensible assumptions.
Martinez distinguishes two concepts. If researchers have a real target population but do not know its exact distribution, the range of values compatible with the data and assumptions concerns partial identification. If several weighting schemes represent different legitimate strategic priorities, the range instead describes normative sensitivity across different targets.
Those cases should not be conflated. A company choosing to give purchase-stage prompts twice the weight of awareness prompts is expressing a business priority. It is not discovering that buyers naturally ask purchase-stage questions twice as often.
A transparent dashboard could show both: a market-estimate score where usage weights are available and a strategic score based on the company’s own priorities.
A citation is not the same thing as contribution
The paper also challenges another common shortcut in AI visibility reporting: treating citation presence as evidence that a source materially influenced the answer.
A model can cite a page without relying heavily on it. Conversely, information associated with a source may influence an answer through retrieval or model knowledge without producing a visible citation.
To study source contribution more rigorously, Martinez proposes a controlled comparison between answers generated with and without a particular source in a fixed documentary context.
That intervention asks a different question from ordinary citation counting: how does the generated answer change when this source is available versus removed?
The paper carefully distinguishes that controlled contrast from manipulating a full production search engine where removing one source can change retrieval competition and cause other documents to enter the answer pipeline. Citation visibility and causal contribution are therefore related but distinct constructs.
This is a methodological critique, not a new market experiment
The paper’s strongest limitation is also stated explicitly by its author. It reports no new experimental data collection.
It is a critical literature survey and methodological analysis supported by reproducible calculations, including the reweighting demonstrator and fictional ranking example. The paper contains 44 references and provides ancillary files with data and code for reproducing its calculations.
But the proposed measurement protocol has not yet been empirically validated across commercial GEO tools, brands or real-world customer populations. The author says its general empirical validity remains to be assessed.
That means the paper should not be cited as proof that a specific vendor’s score is inaccurate. It provides a framework for asking whether that vendor’s score measures what users assume it measures.
GEO vendors should publish a measurement card alongside the score
The most actionable implication is transparency. A visibility percentage without its measurement design is difficult to compare across tools or even across time within the same tool.
A credible GEO report should identify the corpus and its provenance, the situations represented, prompt formulations, weighting rules, engine and execution conditions, repetitions, scoring definition and any LLM judge used to classify answers.
It should also state the denominator. “Share of citations” can mean the brand’s citations divided by all citations globally, the average share within each answer or the percentage of answers containing at least one citation. Those are different quantities and can behave differently when answers contain varying numbers of sources.
If the vendor changes its prompt panel, model mix or weighting scheme between months, a change in the dashboard score may partly reflect the instrument rather than a change in the brand’s underlying visibility.
Brands should ask what market a score actually represents
For marketing teams buying GEO software, the paper suggests a better first question than “What is our AI visibility score?”
Ask what population the score is intended to represent.
Does the prompt corpus come from search-volume data, real assistant logs, customer research, synthetic personas or the vendor’s editorial judgment? Are prompts equally weighted? Does the benchmark distinguish discovery from branded verification? Are languages and countries represented according to actual revenue or usage? Does the system run one-shot prompts or multi-turn journeys? How does it decide that a brand has been cited or recommended?
If those questions cannot be answered, comparing a 62 from one platform with a 48 from another may reveal very little about which platform has measured the market more accurately.
The goal is not one universal GEO score
The paper does not argue that GEO measurement is impossible. Its argument is almost the opposite: useful measurement becomes possible when the target is defined before the number is interpreted.
A controlled benchmark can be valuable for tracking the same brand across a fixed set of strategically important questions. A weighted panel can be useful when a company intentionally cares more about some customer situations than others. A population estimate can be useful when prompt frequencies are tied to a documented usage population.
Those are three different objectives. Trouble begins when the first or second is presented as the third.
Generative engines make the distinction especially important because prompts can affect retrieval, answers and source competition, while another LLM may subsequently determine what counts as visibility. The measurement instrument is not passive.
For GEO, a score without its corpus, conditions and scoring rules is therefore not merely incomplete documentation. It can obscure what the number actually means.
The emerging industry may eventually develop stronger market-level datasets and validated visibility measures. Until then, the most credible GEO dashboard may not be the one that offers the cleanest single score. It may be the one that shows exactly which answer market produced it—and how much the result changes when reasonable assumptions change.