
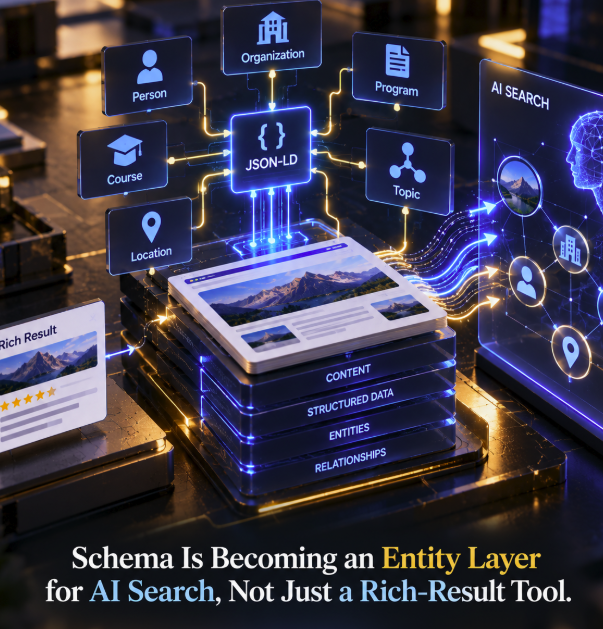
Schema markup is increasingly being treated as more than a mechanism for earning stars, FAQs or other enhanced search appearances. A new Search Engine Land case study argues for a broader role: using structured data as an entity layer that exposes what a website says about its people, organizations, programs, products and relationships — and, crucially, where that information is missing, ambiguous or impossible to verify.
The analysis, published by Ray Martinez on September 18, builds on an earlier entity-gap framework and applies it to two higher-education organizations. In Schema for AI search: Turning entity gaps into organic growth, Martinez describes comparing an intended entity model with the schema and visible content actually present on the sites, then using the discrepancies to guide both markup corrections and content work.
The useful shift is from schema validation to entity reconciliation
Traditional structured-data audits often begin with a narrow question: is the markup valid for a Google rich result? That remains important, but it leaves a much larger semantic question unanswered. A page can contain technically valid JSON-LD while still communicating a weak or incomplete representation of the underlying entity.
The methodology described by Martinez instead starts with the entities an organization wants search engines and AI systems to understand. The audit then compares that target model with the live site, classifying information according to whether an entity is legible, ambiguous or unverifiable. This turns schema from an isolated technical implementation into a diagnostic map of the organization's factual coverage.
In the case studies, the gaps were not abstract. They included details around curriculum, faculty, admissions, financial aid, academic credits, GPA requirements and program modality. Some problems existed in the markup itself; others revealed that the supporting page content did not contain enough precise information to substantiate the intended entity relationship.
Markup cannot repair facts the content does not support
This is one of the most useful lessons in the analysis. Structured data can make an existing fact easier for machines to parse, but it should not become a hidden layer containing claims the visible page cannot support. Google explicitly requires structured data to represent the content of the page and warns against marking up information that is misleading or not visible to users in the appropriate context.
Google's structured data guidelines also make clear that valid markup does not guarantee a rich result. More fundamentally, Google says it uses structured data to understand page content. That framing is useful for AI-search work: schema can clarify meaning, but the underlying content still has to carry the factual evidence.
Martinez's case studies therefore produced different remedies depending on the gap. One organization needed corrections to structured program information and more precise language around requirements. The other needed broader content coverage around outcomes, admissions and curriculum. The entity audit did not automatically prescribe “add more schema”; it identified where the information architecture itself was weak.
Relationships matter as much as individual entities
AI search increases the importance of relationships because many prompts are not simple requests for a page matching a keyword. A user may ask which institution offers a particular program, whether that program has a certain admission requirement, what credential it awards, where it is available or how it compares with alternatives. Answering those questions requires systems to connect entities and attributes rather than merely recognize isolated terms.
Well-designed structured data can express those connections explicitly. An organization can be connected to programs, people, locations and other defined entities; a program can be described through properties that clarify its characteristics; identifiers and consistent references can reduce ambiguity. The goal is not to stuff a graph with every possible schema.org property, but to represent the relationships that are genuinely supported by the site's content.
This is why entity work increasingly looks like information architecture for machines. Content, structured data and internal relationships need to tell a coherent story about what an entity is, what it offers and how it connects to other entities.
The case study reports gains, but it does not prove schema caused them
The results reported by Search Engine Land are notable but need careful interpretation. Martinez says one partner increased measured AI citations substantially over the observation period and improved lead-to-payment and application-to-payment rates. The second organization reported higher organic lead and application volume along with improved AI-citation metrics.
Those outcomes followed entity reconciliation, schema fixes and content changes, but they should not be read as a controlled demonstration that schema markup directly produced the growth. Multiple interventions occurred, the examples come from specific higher-education sites, and search demand, brand activity, seasonality and other variables can affect the metrics.
Martinez makes essentially the same caution in the article: markup does not guarantee growth. The stronger takeaway is methodological. Auditing entities can expose factual and content weaknesses that conventional keyword or schema-validation audits may miss, and repairing those weaknesses can improve the clarity of the experience for both users and machines.
AI visibility makes ambiguous entities more expensive
In a conventional search result, ambiguity may still allow a page to rank because relevance can be inferred from many signals. Generative and conversational systems create an additional challenge: they often need to select facts, connect them to a specific entity and formulate an answer. If the site's representation of an important attribute is vague, inconsistent or unsupported, the system has less reliable material to work with.
This is especially relevant for organizations with similar names, complex product portfolios, multiple locations or offerings whose distinctions matter. A generic statement such as “strong academic record required” is less machine-resolvable than a specific documented requirement. The same principle applies outside education: product compatibility, service areas, professional credentials, event relationships and organizational ownership can all become entity-resolution problems.
The strategic implication is that schema audits should increasingly ask whether the site's most commercially important facts are explicit and reconcilable, not merely whether Google's Rich Results Test returns a green checkmark.
Schema is one layer, not a shortcut into AI answers
There is an important boundary around this trend. Neither the Search Engine Land analysis nor Google's documentation establishes that adding schema is a direct ranking factor for ChatGPT, Gemini, Claude or other AI answer engines. Different systems retrieve, crawl, index and reason over web information in different ways, and some may not consume a site's JSON-LD in the same manner as Google Search.
Calling schema an entity layer therefore describes an SEO and information-modeling strategy, not a new universal AI protocol. The markup can help formalize the site's own entity model and reveal discrepancies between what the organization intends to communicate and what its pages actually support. That is valuable even when the downstream system's exact treatment of schema is unknown.
The durable principle is semantic consistency. Visible content, structured data, internal linking, authoritative external references and first-party identity signals should reinforce the same factual model. Schema is particularly useful because it forces teams to make that model explicit.
Entity-gap audits can become a recurring SEO workflow
Martinez recommends treating entity reconciliation as infrastructure rather than a one-time GEO tactic. That makes sense because entity information drifts. Programs change requirements, companies launch products, executives move, prices and locations change, and pages are rewritten without corresponding updates to structured data.
A recurring audit can begin with the entities and relationships that matter most to the business, compare the desired model against live content and JSON-LD, and classify discrepancies by severity. Some will be technical markup errors. Others will expose missing copy, vague terminology or claims that cannot be verified. Those categories should lead to different fixes rather than an indiscriminate expansion of schema.
Measurement should also extend beyond rich-result impressions. Teams can monitor organic conversions, branded and non-branded discovery, AI citations where reliable measurement is available, changes in entity recognition and the quality of traffic reaching important pages. The purpose is to determine whether better-defined information is helping users and discovery systems understand the organization more accurately.
Rich results are becoming only one reason to care about structured data
Google's official documentation still presents structured data primarily in the context of understanding pages and enabling richer Search appearances. There has been no Google announcement declaring schema a special AI-search ranking mechanism. The emerging methodology is broader: use structured data to make the site's entity model explicit, then use that model to identify gaps in the content itself.
That reframes schema work from “which rich result can this page earn?” to “which entities and relationships does this page need to communicate clearly?” The first question remains useful, but the second is increasingly aligned with a search environment where machines are expected to synthesize facts, compare alternatives and answer multi-step questions.
Schema is not becoming a magic AI-visibility switch. It is becoming a practical way to model, audit and reconcile the entities that AI search systems need to understand. For technical SEO and GEO teams, that may ultimately be a more valuable role than the rich-result mindset that defined structured-data strategy for much of the previous decade.