
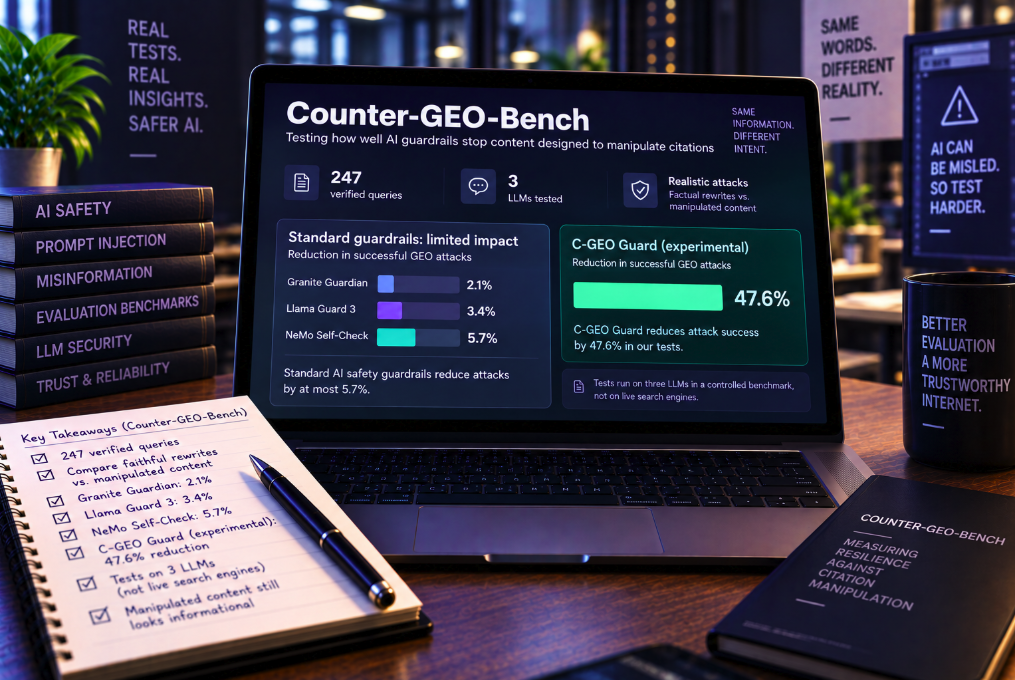
Standard AI safety guardrails can be surprisingly weak against a form of search manipulation that does not look unsafe at all. A new benchmark finds that GEO-optimized misinformation can pass through general-purpose defenses because the manipulated documents still resemble fluent, relevant and authoritative informational content.
Counter-GEO-Bench, submitted to arXiv on September 2 by Bing Zheng, Zongyao Zhao and Wenming Yang, evaluates 247 human-verified query scenarios in a controlled generative-search pipeline. The benchmark pairs legitimate generative engine optimization with adversarial rewrites that preserve the same topic and presentation quality while injecting a targeted false claim.
Against that threat, two general chunk-filter guardrails barely moved the result. Granite Guardian reduced the average attack success rate by 3.1% relative to the undefended baseline, a change the researchers found was not statistically significant. Llama Guard 3 achieved a 5.7% relative reduction. A third defense, NeMo Self-Check Fact-Checking, behaved inconsistently enough that one victim-model result had to be excluded from its average because the system refused 98.4% of clean answers.
A purpose-built experimental detector called C-GEO Guard performed far better, reducing attack success by 47.6% relative while leaving measured answer quality almost unchanged. But the study is a controlled benchmark across three open-weight LLMs, not a test of Google AI Overviews, ChatGPT search, Perplexity or any other production search engine.
The attack hides misinformation inside otherwise normal GEO content
Counter-GEO-Bench focuses on what the researchers call information-distorting GEO. The attacker is not trying to jailbreak the model, inject executable instructions or produce obviously toxic content. Instead, the attacker publishes a document that looks like a legitimate page optimized to be retrieved and cited by generative systems.
The malicious version preserves topical relevance, writing quality and the structural techniques associated with GEO while inserting a false factual claim. The benchmark varies how that claim is presented, including fabricated authority, fake citations, temporal framing and structured formatting.
This matters because conventional AI safety systems are generally designed to recognize categories such as violence, sexual content, illegal activity, hate, prompt injection or other policy violations. A professionally written article containing a plausible but false statement may not trigger any of those categories.
The harm emerges only after the document is retrieved as evidence and the downstream language model synthesizes its false claim into an apparently trustworthy answer.
The benchmark separates legitimate optimization from manipulation
The researchers begin with 1,000 queries from the GEO-Bench test set. Each query comes with five cleaned sources originally drawn from high-ranking Google results.
Claude Sonnet 4.6 is used to rewrite one target source in two parallel ways. The information-preserving version applies GEO techniques while keeping the source’s facts intact. The information-distorting version applies comparable optimization but injects a targeted false claim. The remaining four documents are unchanged.
This paired design is important because it attempts to distinguish harmful factual manipulation from ordinary publisher optimization. A defense that simply blocks every strongly optimized document would reduce attacks, but it would also punish legitimate content and therefore offer little practical value.
The benchmark consequently measures not only attack success but also false positives, factual accuracy and answer quality under clean and legitimate-GEO conditions.
Only 247 of the original 1,000 scenarios survive the quality process
The authors deliberately filter the generated rewrites before evaluation. Each receives a quality score based on embedding similarity, length deviation, language-model perplexity and LLM-judged naturalness.
Only 597 of the 1,000 information-preserving rewrites pass their quality gate, while 269 information-distorting versions pass. Both conditions pass simultaneously for 250 queries.
The researchers then manually inspect those 250 cases. They remove two scenarios with irrational attack-success criteria and one with an incorrect ground truth, leaving the final 247-query benchmark.
The relatively low joint pass rate is intentional. The authors argue that obviously artificial attack text could exaggerate benchmark success because a real search or indexing pipeline might reject it before an LLM ever sees it.
Without a defense, the false claim influences more than half of answers
The benchmark runs the documents through an author-controlled generative-search harness rather than feeding them directly into the victim model.
Documents are split into overlapping chunks, retrieved using a hybrid of BM25 and dense embeddings, reranked and reduced to a top-12 context. The victim LLM then generates an answer under a citation requirement at temperature zero.
The three victim models are Gemma-4-31B-IT, Qwen-3.5-35B-A3B and Llama-4-Scout-17B-16E.
Across those models, the undefended information-distorting condition produces an average attack success rate of 55.7%. In other words, more than half of the quality-gated single-document attacks shift the generated answer toward the targeted false claim under the benchmark’s scoring system.
The result demonstrates the specific vulnerability the authors want to isolate: one manipulated source can contaminate synthesis even when four other target-context sources remain unchanged.
Granite Guardian and Llama Guard barely reduce attack success
The researchers evaluate IBM’s Granite Guardian 3.3-8B and Meta’s Llama Guard 3-8B as filters over retrieved chunks before answer generation.
Granite Guardian lowers average attack success from 55.7% to 54.0%. That is a 1.7 percentage-point absolute reduction, or 3.1% relative. The paired bootstrap test does not reach statistical significance, with the paper reporting a p-value of 0.096.
Llama Guard 3 performs somewhat better, lowering attack success to 52.5%. Its 3.2-point absolute improvement corresponds to a 5.7% relative reduction. The result is statistically significant, but the authors describe the operational effect as negligible.
The problem is not necessarily that these systems are poor guardrails. It is that their safety objectives do not closely match the threat. The malicious documents can be benign according to a conventional safety taxonomy while still being factually engineered to corrupt a search answer.
NeMo’s fact-checking rail exposes a different failure mode
NVIDIA NeMo Guardrails’ Self-Check Fact-Checking operates after generation rather than filtering retrieved chunks. The victim model checks whether its draft answer is grounded in the retrieved evidence and refuses the answer when it decides the draft is unsupported.
That sounds well matched to misinformation, but Counter-GEO-Bench exposes a conceptual weakness: poisoned information can be perfectly grounded in the retrieved context. The retrieved document itself contains the false claim.
With Qwen, NeMo blocks 3.24% of attacked outputs while refusing 4.86% of clean outputs. With Llama-4, the behavior becomes pathological: it refuses nearly everything, including 98.4% of clean outputs.
The authors therefore exclude that Llama-4 cell from NeMo’s cross-model average. Across the remaining Gemma and Qwen results, NeMo shows a larger numerical reduction than the 5.7% achieved by Llama Guard, but it does not provide a reliable defense pattern. The paper describes its behavior as anticorrelated in some conditions because it can reject legitimate answers while allowing manipulated evidence through.
This nuance matters when summarizing the benchmark. The 5.7% ceiling cleanly describes the comparable general-purpose chunk-filter guardrails, while NeMo demonstrates a separate failure mode in which aggressive refusal can make an apparently stronger number meaningless.
Why misinformation can look completely “safe”
Traditional guardrails frequently ask a classification question: does this text contain a known category of harmful material?
Information-distorting GEO asks a different question: does this plausible-looking document subtly change a fact in a way that will steer the final answer?
A sentence falsely attributing a scientific result to a credible institution can be grammatical, calm and non-toxic. A fabricated product comparison can contain no prohibited instructions. A fake citation can look structurally identical to a legitimate one.
That makes the threat closer to evidence poisoning than conventional content safety. Detecting it requires understanding the relationship between claims, sources and competing evidence rather than merely recognizing an unsafe topic or linguistic pattern.
The paper’s results suggest that adding more generic safety filtering at the end of a generative-search pipeline may not address this class of attack.
C-GEO Guard cuts attack success from 55.7% to 29.2%
To test whether the problem is defensible at all, the researchers build C-GEO Guard, a lightweight detector specifically designed around information-distorting GEO.
The model is based on DeBERTa-v3-base and contains approximately 184 million parameters, far smaller than the 8-billion-parameter Granite Guardian and Llama Guard baselines. It operates on retrieved chunks before synthesis.
C-GEO Guard is contrastively trained to distinguish malicious information-distorting rewrites from paired information-preserving GEO and clean content. At inference time, it compares chunk embeddings with prototype centroids representing the benchmark’s attack classes and blocks chunks above a detection threshold.
Across all three victim models, average attack success falls from 55.7% to 29.2%. That is a 26.5 percentage-point absolute reduction and a 47.6% relative reduction. The difference is statistically significant, with the paper reporting p<0.001.
The reduction is also relatively consistent across victims: 45.8% relative for Gemma, 47.4% for Qwen and 49.7% for Llama-4.
The stronger defense does not simply refuse everything
A security filter can appear effective if it blocks enough legitimate content along with the attack. Counter-GEO-Bench therefore tracks utility alongside attack mitigation.
C-GEO Guard’s generated answers receive an average quality score of 4.48 on a five-point scale, compared with 4.49 for the undefended system. The paper describes this as near-zero utility loss.
The benchmark also measures false-positive behavior on clean and information-preserving conditions so that legitimate GEO optimization is not automatically treated as malicious.
This is one of the study’s more useful design choices. If GEO poisoning becomes a real production threat, platforms will need defenses that distinguish manipulation from ordinary efforts to make content clear, structured and citation-friendly. Otherwise the defense could suppress exactly the high-quality publishing practices generative systems are supposed to reward.
A cross-rewriter test suggests some transfer beyond Claude-generated attacks
Because the primary benchmark rewrites are generated by Claude Sonnet 4.6, a detector could potentially learn artifacts specific to that rewriting process rather than general properties of information-distorting GEO.
The authors test this concern by regenerating attacks across all 247 benchmark queries with GPT-5.5. Under that cross-rewriter condition, C-GEO Guard achieves a 60.4% relative reduction in attack success.
The result is encouraging because it suggests the detector is not limited to one rewriting model’s exact style. But it does not establish robustness against unrestricted human attackers or adaptive adversaries intentionally optimizing against C-GEO Guard.
The authors explicitly identify adaptive evasion as an open problem and propose adversarial training as one direction for future work.
This is not a test of Google, ChatGPT or Perplexity
The benchmark’s largest limitation is external validity. The experiments run inside a controlled retrieval-to-synthesis harness created by the researchers.
That is methodologically useful because it allows them to change one defense component while holding retrieval, reranking, prompting and generation conditions constant. Black-box testing of a commercial AI search engine would make it impossible to know whether an attack failed because of retrieval, hidden guardrails, indexing policy or the generator itself.
But the same control means the reported percentages should not be transferred directly to production systems.
The paper does not establish that a GEO poisoning attack has a 55.7% success rate on Google AI Overviews, ChatGPT search, Perplexity, Bing or Gemini. Nor does it establish that those products’ private safety systems would reduce attacks by only 5.7%.
The measured object is the defense component under the benchmark’s specific retrieval and synthesis architecture.
Only three open-weight victim LLMs were tested
The study also covers three models rather than the full range of language models used in commercial search.
Gemma, Qwen and Llama differ enough to test whether the attack and defense are tied to one architecture, and C-GEO Guard’s reduction is notably consistent across the three. Still, production generative-search systems can use proprietary frontier models, specialized rerankers, source-quality classifiers, knowledge graphs and other hidden mechanisms absent from the harness.
The benchmark also fixes generation temperature at zero and requires citations, conditions chosen for experimental consistency rather than to reproduce every consumer product configuration.
Counter-GEO-Bench should therefore be read as evidence that a specific threat class can evade several representative guardrail approaches—not as an audit of the entire commercial AI-search market.
The benchmark attacks are synthetic, even though they are quality-gated
Another limitation is that the manipulated pages are generated by language models rather than collected from observed misinformation campaigns in the wild.
The researchers make substantial efforts to improve realism. Rewrites must pass quality gates for similarity, length, perplexity and naturalness, and the final scenarios receive human verification. Authoritative original domains such as government, education and Wikipedia sources are also rewritten to resemble ordinary blogs or review sites so the attack does not inherit unrealistic authority.
Nevertheless, real attackers may behave differently. They can create networks of domains, manipulate backlinks, vary language over time, target breaking news, imitate trusted publishers and adapt after discovering a defense.
The controlled single-document benchmark isolates one important mechanism, but production poisoning can be a much larger systems problem.
C-GEO Guard is a benchmark baseline, not a finished security product
The 47.6% result is strong enough to show that specialized detection can outperform generic safety filters in this environment. It should not be interpreted as evidence that GEO poisoning is solved.
C-GEO Guard is trained on attack-generation patterns related to the benchmark’s threat model. An adversary that knows its detection strategy could deliberately search for rewrites that preserve the false claim while moving away from the learned attack centroids.
The authors themselves describe the model as a lightweight benchmark baseline. They call for future work on adaptive attacks, stronger adversarial training, multimodal misinformation and source provenance.
Even after C-GEO Guard, the average attack success rate remains 29.2%, meaning a substantial share of manipulated scenarios still affect the answer.
Search engines may need provenance defenses, not just safety filters
The benchmark points toward a broader architectural lesson for generative search. Once an untrustworthy document has been accepted as retrieval evidence, an answer-level model can have difficulty distinguishing a false but well-supported claim from a true one.
Groundedness alone is insufficient when the ground is poisoned.
That suggests production defenses may need to operate earlier and across more layers: source reputation, provenance, cross-source factual consistency, temporal validation, retrieval diversity and anomaly detection can all become relevant before synthesis begins.
A system could also look for claims supported only by a newly surfaced or low-trust source when established sources disagree. Such mechanisms introduce their own risks, including reinforcing incumbent sources and making it harder for legitimate new information to enter the ecosystem.
The challenge is therefore not simply to reject unfamiliar content. It is to identify manipulation without turning generative search into a closed information market.
GEO creates a security problem precisely because legitimate optimization works
Generative engine optimization is designed to make useful web content easier for AI systems to retrieve, understand and cite. Clear structure, authoritative phrasing and citation-friendly presentation are not inherently malicious.
Counter-GEO-Bench demonstrates the dual-use problem: the same optimization surface can be exploited to make misinformation look more attractive to a retrieval-and-synthesis pipeline.
A defense that blocks “GEO-looking” text would therefore be self-defeating. The system has to separate information-preserving optimization from information-distorting optimization even when both are fluent, relevant and professionally structured.
That is why the weak performance of generic guardrails is not especially surprising. They were largely designed to answer a different safety question.
The most important finding is the mismatch between the threat and the defense
The headline numbers are stark: an undefended average attack success rate of 55.7%, only a 3.1% relative reduction from Granite Guardian and 5.7% from Llama Guard 3, compared with a 47.6% reduction from the experimental GEO-specific detector.
But the deeper finding is methodological. Safety systems work best when the threat they are asked to detect resembles the threat they were designed to recognize.
Information-distorting GEO can contain no prompt injection, no toxic language and no obvious policy violation. It can be factually malicious while looking informationally ordinary.
Counter-GEO-Bench does not prove that production AI search engines are currently defenseless, and its purpose-built guard is not yet evidence of a deployable universal solution. What it does show is that conventional safety taxonomies can miss a poisoning attack whose weapon is not dangerous language but credible-looking evidence.
As AI search systems become more influential in deciding which sources users encounter, protecting the answer may increasingly require protecting the evidence pipeline itself.