
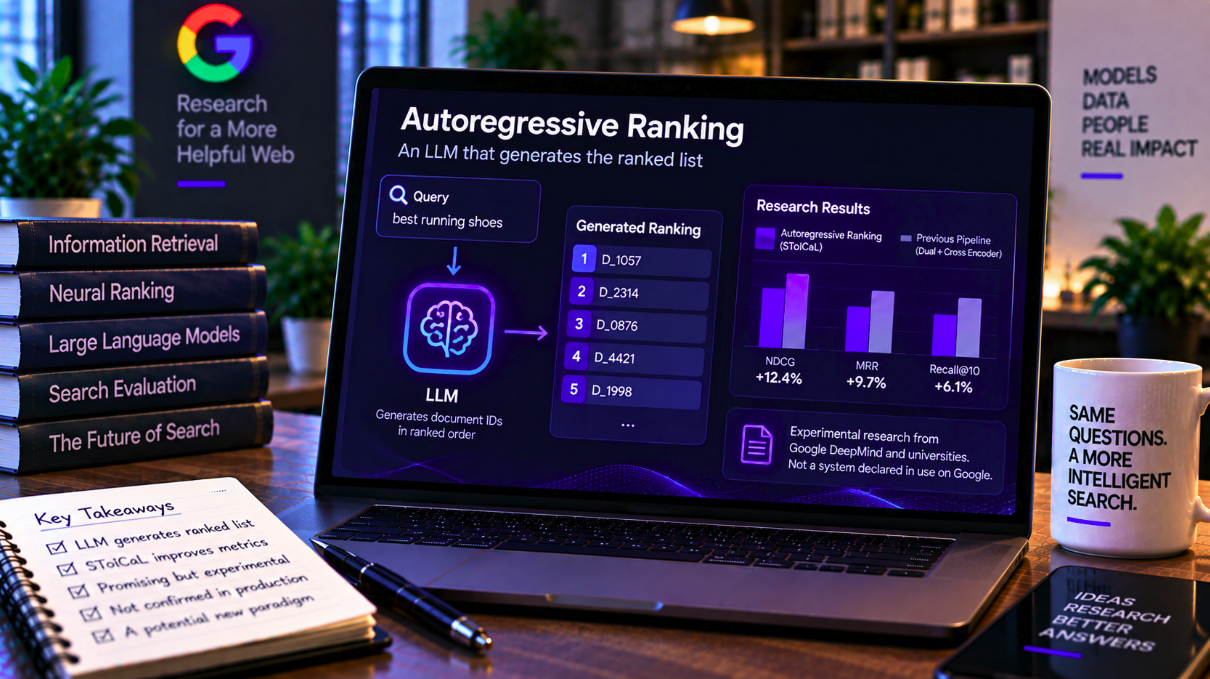
Most modern neural search systems separate speed from precision. A dual encoder can retrieve candidates efficiently from a large collection, while a more computationally expensive cross encoder can examine those candidates more deeply and rerank them. Researchers affiliated with Google DeepMind, the University of Massachusetts Amherst and the University of Texas at Austin are exploring a more radical alternative: let a language model generate the document identifiers that belong at the top of the ranked list.
The approach, called Autoregressive Ranking (ARR), is described in the paper “Autoregressive Ranking: Bridging the Gap Between Dual and Cross Encoders”. Rather than representing every query and document as vectors and then separately reranking retrieved candidates, ARR models the probability of document IDs token by token. With beam search, the system can generate the highest-probability document identifiers directly, producing a ranking through autoregressive decoding. A Search Engine Journal analysis describes the idea as a possible alternative to the familiar dual-encoder/cross-encoder architecture, but the distinction between “possible” and “deployed” is essential: the paper is experimental research, not an announcement about Google Search’s production ranking system.
Why generate document IDs instead of scoring every candidate?
Dual encoders are attractive because queries and documents can be embedded independently, allowing fast approximate-nearest-neighbor retrieval. Their limitation is that the interaction between the query and document is compressed into a vector similarity. Cross encoders can model that interaction more richly because they process the query and document jointly, but doing so for every document in a massive corpus would be prohibitively expensive. The conventional compromise is therefore a multi-stage system: retrieve efficiently, then spend more computation on a smaller candidate set.
ARR asks whether generation can bridge that gap. Each document is represented by a docID consisting of one or more tokens, and the language model learns a conditional probability for those token sequences given a query. Because autoregressive decoding can search for high-probability sequences without exhaustively scoring every document one by one, the researchers argue that the architecture could combine richer modeling with a more unified retrieval-and-ranking process. In their formulation, it can also eliminate the need for the separate approximate-nearest-neighbor index used by dual-encoder retrieval.
The paper’s strongest theoretical result concerns expressive capacity rather than measured web-search performance. Under an idealized “complete ranking” task, the authors prove that a dual encoder needs an embedding dimension that grows linearly with the number of documents if it must be capable of representing arbitrary orderings. Under stated conditions on the docID token embeddings, an autoregressive ranker can theoretically represent arbitrary rankings while keeping its hidden dimension constant. That is a mathematical explanation for why generation can be more expressive than vector similarity, not proof that an ARR system would automatically be faster, cheaper or better on a production search engine containing billions of changing documents.
SToICaL teaches next-token prediction that rank order matters
Generation creates a second problem: ordinary next-token training is not designed to care about the quality of an entire ranking. Predicting the correct token sequence for a relevant document does not by itself teach a model that document A belongs above document B. The researchers address this with SToICaL, short for Simple Token-Item Calibrated Loss, a rank-aware generalization of the standard next-token objective.
SToICaL introduces relevance at two levels. First, item-level reweighting gives higher-ranked documents more influence during training. Second, a prefix tree over tokenized document IDs identifies which token continuations can still lead to valid documents and allows probability mass to be distributed according to the relevance of those possible destinations. The goal is not merely to make the model reproduce identifiers, but to shape its probability distribution so beam search naturally favors the documents that should appear higher in the list while suppressing invalid or irrelevant outputs.
Experiments on WordNet and Amazon’s ESCI Shopping Queries support parts of that argument. The authors report that their rank-aware loss improves several ranking metrics beyond top-1 retrieval and sharply reduces cases in which irrelevant documents outrank relevant ones. In a WordNet comparison, ARR performed similarly to the tested cross encoder and significantly better than the dual encoder in the reported setup. The gains were not universal, however: as Search Engine Journal notes, one shopping-search configuration became worse at placing the single most relevant result first even while improving broader ranking quality. That trade-off is important because it prevents the research from being summarized as a clean across-the-board victory.
This is not evidence that Google Search now ranks the web with an LLM
The Google affiliation makes the work particularly interesting to search marketers, but it also creates the easiest path to overstatement. Nothing in the paper establishes that ARR or SToICaL is running in Google Search, replacing an existing Google ranking system or scheduled for deployment. Academic and industrial research groups routinely investigate architectures that never become production products, and a controlled ranking benchmark leaves out many constraints that determine whether a method can operate at web scale.
The experimental setup itself deserves attention. The authors test WordNet and ESCI rather than a live web index, and parts of the work use in-context ranking in which a pool of document IDs is supplied to the model in the prompt. The theory is intended to apply more broadly, including parametric generative retrieval, but demonstrating expressive capacity and benchmark improvements is different from maintaining a continuously changing search corpus under strict latency and cost limits. Real search infrastructure must also handle indexing, freshness, language and location, spam and safety, duplicate content, access constraints and many other systems beyond the ranking abstraction studied here.
For SEO, the paper is therefore more useful as a view of a possible architectural direction than as a new optimization playbook. If generative ranking eventually becomes practical at large scale, the conceptual change would be significant: document selection would be encoded in a model’s token probabilities rather than expressed only through vector retrieval followed by candidate scoring. But the paper provides no basis for concluding that keywords, links, structured data or any other familiar signal should be changed today because of ARR. It studies how a ranking machine can represent and learn ordered relevance, not which web-page characteristics Google rewards.
The broader research question is compelling nonetheless. LLMs are usually discussed in search as systems that generate the answer after retrieval. Autoregressive Ranking moves generation deeper into the information-retrieval stack by asking an LLM to generate the identities of the documents themselves. SToICaL then tries to make that generation explicitly sensitive to ranking quality rather than treating relevance as an accidental consequence of next-token prediction.
That makes the work worth watching without turning it into a premature Google algorithm update. The experiments show that a generative ranker can outperform simpler retrieval architectures on important measures and approach a cross encoder in one reported comparison, while also exposing trade-offs on other metrics. The theory shows why autoregressive models can have greater ranking capacity under idealized assumptions. What remains unanswered is the hardest part: whether those advantages survive the cost, scale, freshness and reliability requirements of real-world search. For now, ARR is a provocative research model for what ranking could become—not evidence that Google has already replaced the pipeline behind its results.